

Insights
How to Prevent an LLM from Accessing Confidential Development Data
Keep confidential data out of LLM context with isolated workspaces, sanitized inputs, retrieval authorization, tool permissions and boundary tests.
Prevent an LLM from accessing confidential development data by withholding that data from its context and restricting the permissions of the software running it. Use a sanitized development workspace, synthetic test data, narrowly scoped agent credentials, authorized retrieval and externally enforced tool permissions.
Keep secrets out of prompts, logs and training datasets. A “never reveal secrets” instruction, a training opt-out or an encrypted connection does not prevent the model from processing data you send it.
Define what the assistant must never receive
Start with the data boundary, then choose controls for each route into the assistant. Confidentiality checks must cover proprietary content as well as personally identifiable information, or PII.
- Classify prohibited data. Include credentials, customer records, proprietary source code and unreleased designs. Decide which material can appear in an approved development copy and which must remain inaccessible.
- Identify entry points. A coding assistant may read workspace files or terminal output. An application agent may retrieve documents, query databases or call tools using credentials supplied by its runtime.
- Choose enforcement before model context. Apply file isolation, ingestion checks, retrieval authorization or tool-execution checks before content reaches the model. Grant access only to data needed for the specific user or process.
Use a small inventory to make those boundaries explicit:
| Entry point | Confidential content at risk | Control before model access |
|---|---|---|
| Prompts | Pasted records or designs | Review and sanitize input |
| Files | Credentials or restricted code | Approved workspace and restricted mounts |
| Terminal output | Environment values or diagnostic records | Restrict commands and sanitize results |
| Connectors | Private documents or database rows | User-specific authorization |
| Logs | Prompt traces and tool results | Sanitize before storing or reusing |
Workspace and runtime restrictions are the starting point for coding assistants. Retrieval authorization and tool gating become essential when an assistant has connectors, database access or execution tools.
Give the assistant a sanitized development workspace
Give the assistant an allowlisted working copy containing only approved source, documentation and synthetic test fixtures. This is easier to reason about than a sensitive workspace with exclusions added afterward.
- Build the approved copy. Include the files needed for the task, not the entire development environment. Keep production exports, private keys,
.envfiles and confidential documents outside its accessible filesystem. - Restrict the runtime. For agents with shell access, use an isolated runtime with only required filesystem mounts. Do not inherit production credentials from the host environment.
- Check tool-specific exclusions. Repository ignore files govern repository behavior; do not assume they govern an assistant’s file access. Confirm whether documented exclusions cover direct reads, indexing, search and shell tools.
- Verify the boundary. Place a harmless marker in a prohibited test file and attempt access through each enabled route. If any route returns it, fix that route before introducing confidential material.
An agent with shell access needs sandboxing and oversight when it can access the system. Hiding a file from an editor view does not establish that the agent’s runtime cannot read it.
For example, an approved code copy can use synthetic fixtures while the original production export stays outside all mounted directories. These are general implementation steps, not universal editor settings.
Remove sensitive content before prompts, indexing and training
Sanitize data before it enters a prompt, document index or training dataset. Filtering the answer happens too late to prevent the model from accessing confidential input.
- Scan approved inputs. Review code, documentation, logs and connector content before ingestion. Look for recognizable secrets and organization-specific confidential material.
- Replace or remove sensitive content. Use synthetic records instead of customer exports. Redact restricted design details and proprietary content, not just credential patterns.
- Keep credentials outside model-visible results. Store operational credentials in a secrets manager. A tool can use an authorized credential without returning its value to the assistant.
- Sanitize retained copies. Apply checks to prompt traces, retrieved context and persisted summaries before they are stored or reused.
Scrub data, vault secrets and monitor AI logs before connecting internal systems. Pattern-based detection can miss sensitive material, especially when confidentiality comes from business context rather than recognizable formatting. Add organization-specific rules and human review for that content.
Review provider processing, retention, training and third-party-tool policies separately. A training opt-out concerns training use, not whether the service processes your request; self-hosting likewise does not stop your own model from receiving submitted data. Recheck the applicable controls when integrations change because platform interfaces and control mechanisms continue to evolve.
Runtime permissions can block future retrieval, but fine-tuning requires dataset hygiene before training. Changing retrieval permissions afterward does not remove confidential material from trained weights.
Enforce permissions on retrieval and tool execution
Put access decisions in application code or an authorization service, outside the model. Treat a model-generated tool call as a proposed action, not permission to execute it.
- Use separate development identities. Give each workflow only the resources and operations it needs. Avoid supplying a developer’s broad production credentials.
- Allowlist tools and validate arguments. Permit narrow operations against approved resources. Prefer APIs returning approved fields over arbitrary SQL or unrestricted shell access.
- Authorize every execution. Look up the authenticated user’s permissions and check the proposed resource and operation before running the tool.
- Authorize retrieved content before context. Filter searches by the asking user’s permissions, then recheck access to each source document before adding its content to the prompt.
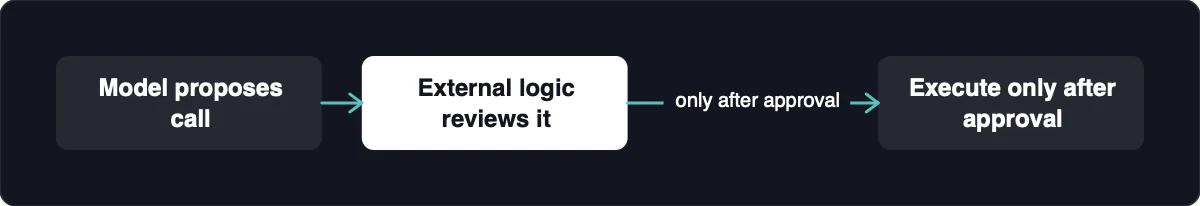
Use a proposal-review-execute pattern: the model proposes a call, external logic reviews it, and execution happens only after approval. Do not infer the user’s authorization from model output.
For retrieval-augmented generation, where retrieved documents are added to model context, an index filter is not the final authority. Check current document access against the source system before including a retrieved chunk. An older index entry may not reflect a later permission change.
Read-only credentials still permit reading and potential disclosure. If a sensitive read requires human approval, obtain that approval before retrieval, not after the model receives the result. Apply the same external checks to database tools, APIs and tools exposed through MCP.
Keep sessions, caches and derived data isolated
Treat summaries, embeddings and cached tool results as potentially confidential records. Moving information out of the original document does not make it safe to share across users or environments.
- Attach boundary metadata. Key persisted state by the applicable tenant, user and environment. Write tenant metadata with embeddings and filter similarity searches by it.
- Enforce boundaries on reads and writes. Separate development from production stores, and avoid sharing agent contexts between users with different permissions.
- Manage derived copies. Give summaries, caches and indexes retention rules and deletion paths linked to the original records. Every derived store needs a retention period and a reachable deletion path.
For example, a cached document summary must not become available to another user simply because it is shorter than the original. Check the requester’s permissions before loading it into context, and account for changed permissions when reusing stored results.
A tenant-aware output check can catch some mistakes, but it is a backstop. It cannot replace authorization before the model receives another tenant’s content.
Restrict network reachability without confusing it with data access
Make development services reachable only by intended devices and identities, then enforce resource permissions separately. Network controls limit where an agent can connect; application controls determine what it may read or execute after connecting.
Use firewall rules to restrict service access and outbound-destination controls to limit unnecessary connections. Test both permitted and denied paths. An allowed destination can still receive a sensitive payload, so destination filtering must accompany input sanitation and tool authorization.
For private connectivity, doxx.net is a private network with firewalls, domain filtering, private domains, private PKI certificates, agent identity and authorized API/MCP tools for network management. Those documented capabilities support network configuration; you still need application-level checks for database rows, documents and application tools. If you need that connectivity, use the website’s Get Started and Download paths to create an account, download the app and connect a device or agent.
Encryption protects transport, but it does not conceal a request from the receiving model service. Private connectivity does not prevent prompt injection or all data leakage. Keep the model’s proposed actions subject to external authorization even when the connection itself is private.
Verify denied access with harmless test data
Test the configured boundaries in an authorized environment using harmless, unique markers, never live credentials. Use a low-privilege account rather than the account that built the assistant, so broad development permissions do not hide failures.
- Prepare permitted and prohibited test resources. Put markers in test files, documents and caches with deliberately different access permissions.
- Exercise each enabled route. Test file reads, retrieval, tools, network connections and session state.
- Inspect the control decisions. Check retrieval results, execution decisions and sanitized request traces, not just the model’s answer.
- Correct failures and repeat. Suspend the affected integration, fix the boundary and rerun both denied and allowed tests.
| Test | Expected evidence | Corrective action |
|---|---|---|
| Read an excluded file | Runtime denial or file unavailable; marker absent from model input | Fix workspace exposure, mounts or tool exclusions |
| Retrieve another user’s document | Authorization rejects it before context assembly | Fix search filters and source-permission checks |
| Invoke a denied tool | External gate rejects execution | Fix identity permissions and operation validation |
| Connect to an unapproved endpoint | Network control blocks the connection | Correct destination restrictions |
| Read another session’s cache | Cache access denied; marker absent from context | Fix session keys and read authorization |
| Use an approved file or tool | Authorized content arrives or operation succeeds | Repair the integration if the allowed path also fails |
A refusal such as “I cannot reveal that” does not prove the model lacked access. Prompt restrictions can be bypassed, so inspect whether prohibited content entered context at all. Passing these tests supports the boundaries tested; it is not a guarantee against every leak or attack.
If confidential data has already reached the model
Stop the affected workflow and treat the submission as a disclosure requiring review. Changing a prompt or permission can prevent future access, but it cannot undo what the model already received.
- Contain access. Suspend the affected connector, tool or workflow. Notify the responsible security team or data owner through your authorized incident process.
- Revoke or rotate exposed credentials. If a usable credential was submitted, address that credential rather than relying on conversation deletion.
- Trace retained copies. Review conversations, logs, caches, indexes and downstream services. A secret exposed in logged processing steps can create multiple leaked copies.
- Use available deletion mechanisms. Check their documented scope and address derived stores through their deletion paths. Do not assume deleting a conversation removes provider records, downstream copies or trained model content.
Preserve the incident information your authorized process requires without spreading the confidential payload into new tickets or logs. Record which boundaries failed, which copies were addressed and which deletion limits remain.
If confidential material entered fine-tuning data, runtime authorization is not a removal mechanism. Address the affected dataset and model through the responsible owner’s procedures; dataset hygiene belongs before training, not after deployment.
